Airflow files
Airflow runs a real standalone scheduler and LocalExecutor. Scala/Python containers exchange Arrow IPC files; XCom carries paths. Retries are disabled.
 XStream
PERFORMANCE BENCHMARKS
Real Scala/Python operators, identical workloads, independently verified outputs. Compare file handoffs, model tool scheduling and streaming execution.
Measured on 5 November 2026 · 250,000 observation rows · 48 runs including warmups
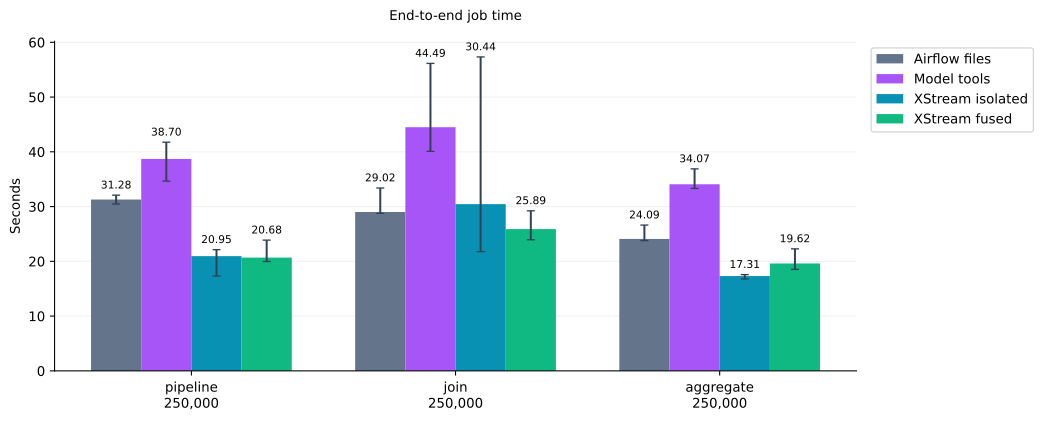
Seconds, median of successful measured runs. Lower is faster.
| Workload | Airflow files | LangGraph + model tools | XStream isolated | XStream fused |
|---|---|---|---|---|
| CSV filtering | 31.284 | 38.702 | 20.948 | 20.679 |
| Station Join | 29.016 | 44.494 | 30.443 | 25.890 |
| Grouped aggregation | 24.095 | 34.072 | 17.309 | 19.616 |
Failed runs including warmups: 0. Failed trials remain in raw records and are excluded from successful-run medians.
Airflow runs a real standalone scheduler and LocalExecutor. Scala/Python containers exchange Arrow IPC files; XCom carries paths. Retries are disabled.
LangGraph asks the model to choose ready steps, executes actual Scala/Python tools and returns result handles. API waits and the final model response are included. Data payloads stay outside the model context.
Model: gpt-6.1-sol
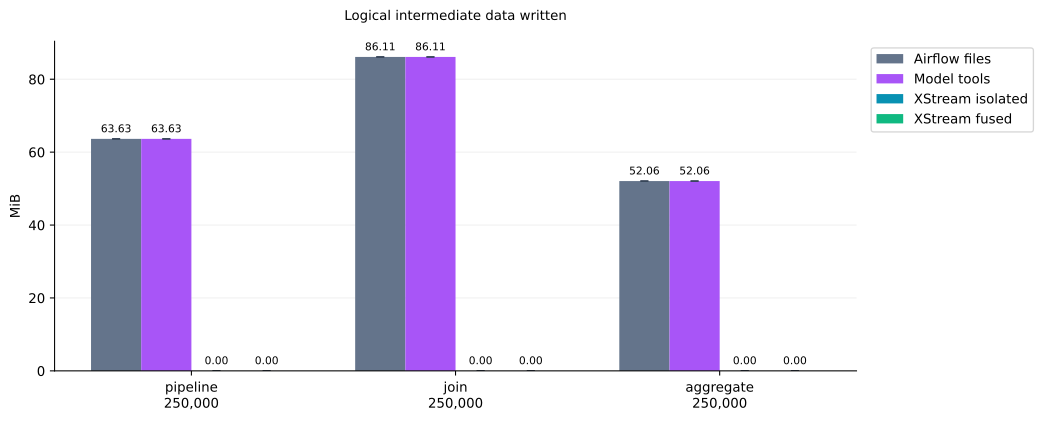
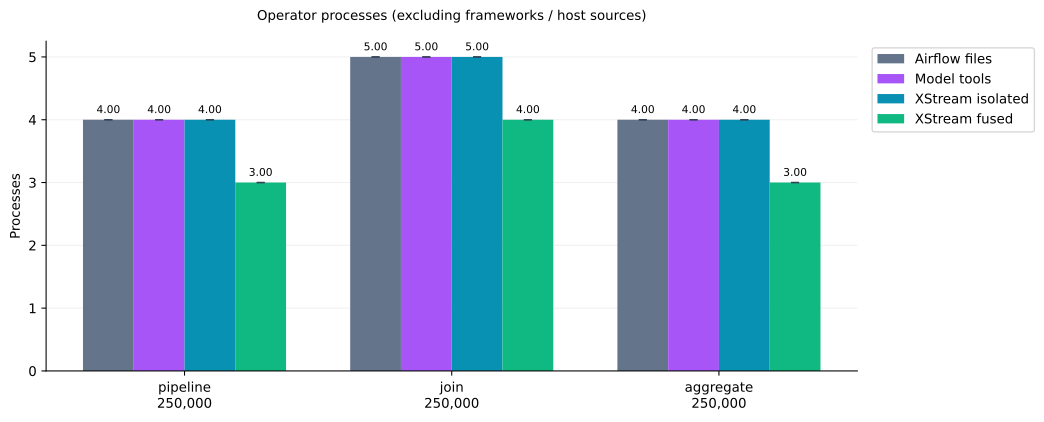
The same Scala/Python operators exchange streams without intermediate data files. Isolated mode uses separate processes; fused mode places compatible steps in a shared JVM.
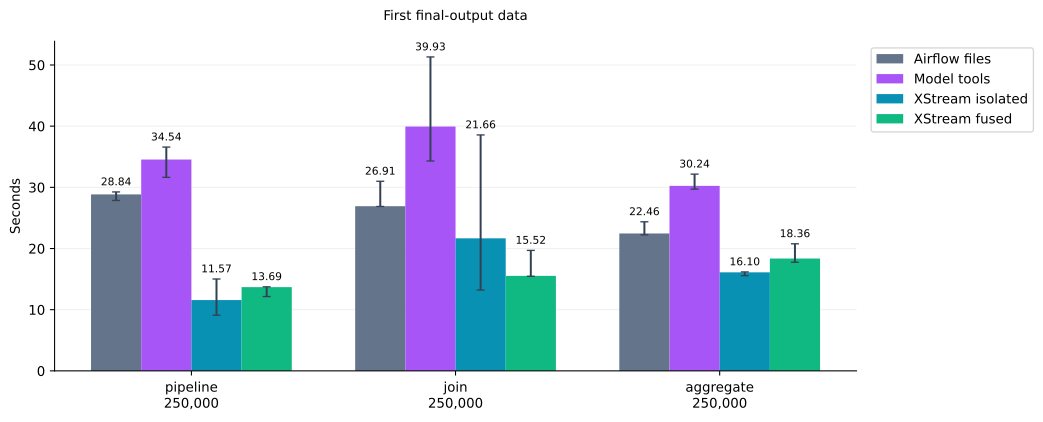
Bars show successful measured medians; whiskers span minimum to maximum, not confidence intervals.
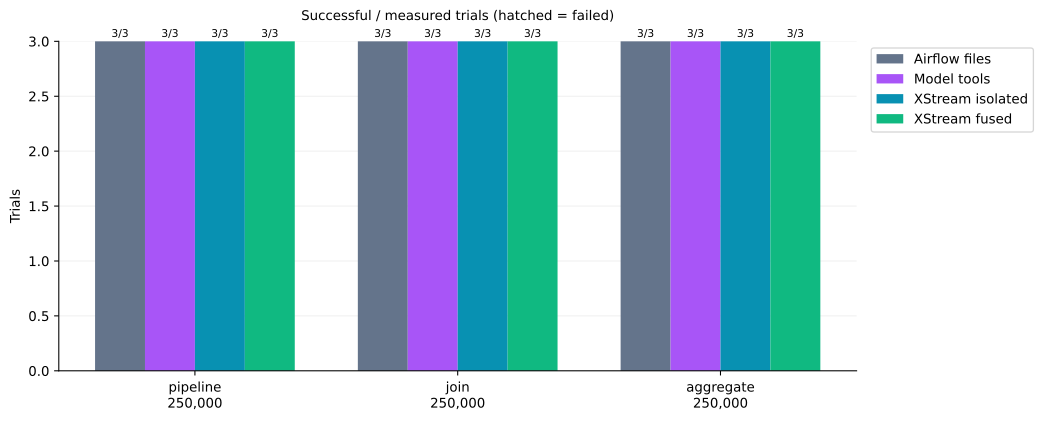
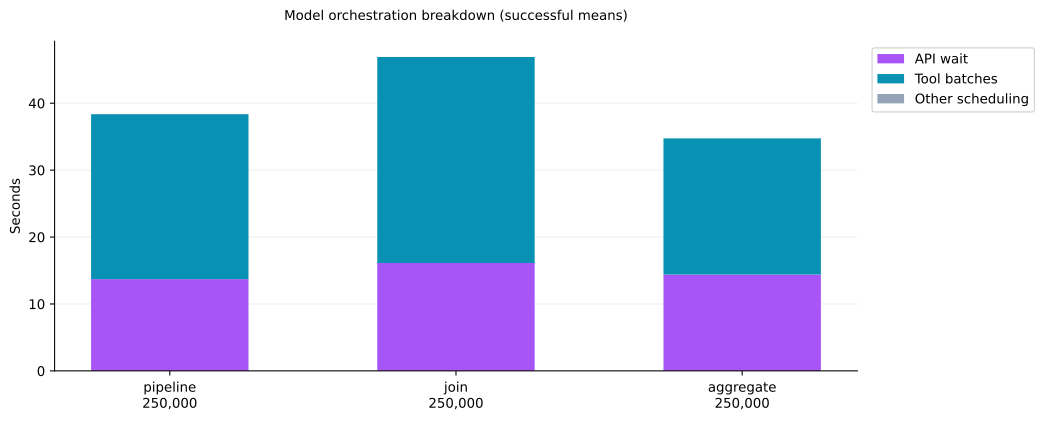
| Workload | Successful / attempted | API wait (s) | Total tokens |
|---|---|---|---|
| CSV filtering | 3/3 | 14.458 | 3710 |
| Station Join | 3/3 | 16.213 | 4193 |
| Grouped aggregation | 3/3 | 14.322 | 3840 |
API latency depends on the provider, network and load. Token counts are usage, not a price estimate.
Every method executes the same fixed DAG using the same Scala/Python operator packages and runtime images. This measures runtime scheduling, not the quality of natural-language workflow generation.
Each combination has one warmup and three measured attempts. Scheduling, container startup, computation, serialization and complete output consumption are timed. Input generation, downloads and framework startup are excluded.
These are specific integrations on a shared 16-vCPU host. Airflow does not require files. Different adapters and process layouts contribute to the results; streaming alone is not always faster. Files use OS buffering without fsync, so this is not a durability or physical disk-I/O comparison.
Every successful output is checked against an independent Python implementation for SHA-256, byte length and row count. The raw records include failures, individual timings, model usage, actual tool-call order and artifact hashes.